Hi, I'm Azim 👋
The cell is a highly mysterious intelligent machine that fascinates my imagination and arouses my curiosity. As a Principal AI Scientist at Johnson & Johnson Innovative Medicine, I develop machine learning methods that help us understand and simulate it, from deep multimodal representation learning to building virtual cells. My work integrates genomics, spatial transcriptomics, imaging and proteomics into foundation models grounded in biological priors such as pathways and regulatory networks. The goal is models that not only predict how cells respond to perturbations but also reveal the mechanisms behind those responses, accelerating drug discovery in oncology and immunology.
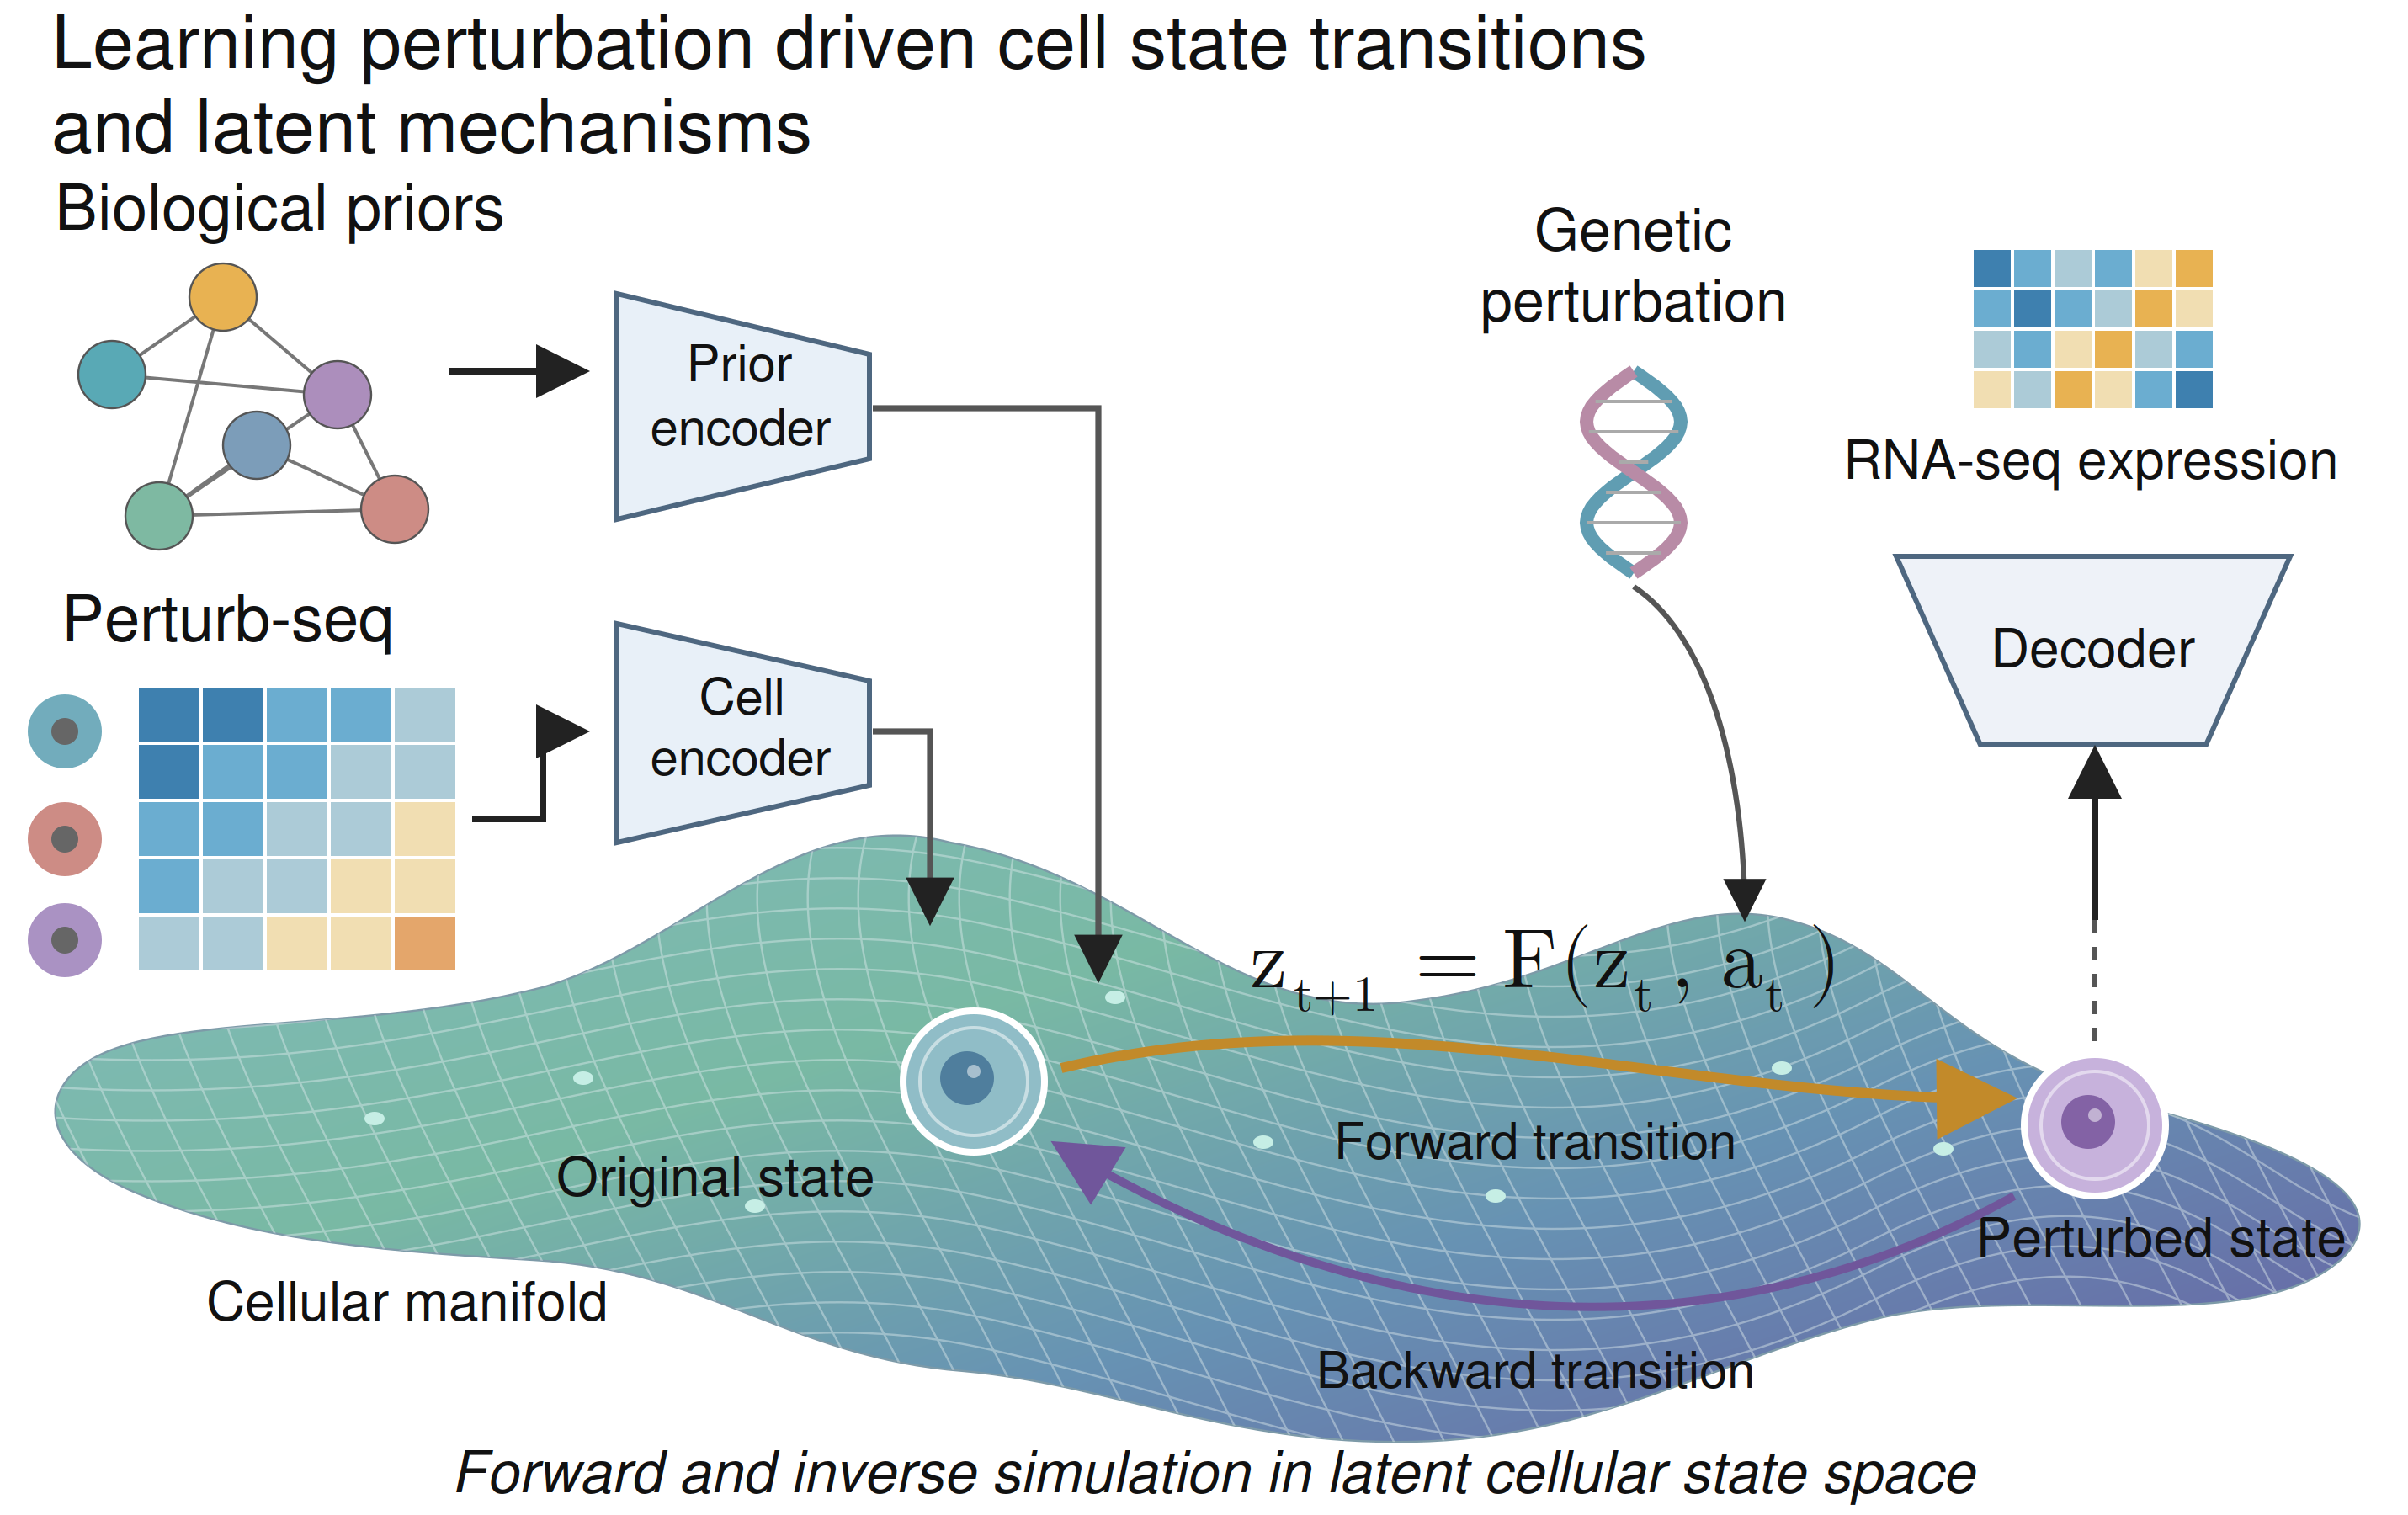
A virtual cell is a computational model that simulates how a cell behaves and responds to interventions such as genetic perturbations or drugs, enabling biological experiments to be explored in silico before they are run in the lab. A core capability of such models is predicting how a cell's molecular state changes under perturbation. Most existing approaches map a baseline profile and a perturbation directly to an outcome, skipping the cellular transition in between. VCLMU instead represents cell state as a set of Latent Mechanism Units (LMUs), each pairing a reusable identity grounded in multimodal biological evidence with an observation-specific state, and treats perturbations as actions that drive mechanism-specific transitions in this latent space. Pretrained on ~200K pseudo-bulk profiles and then on single-cell perturbation data, VCLMU improves perturbation-specific response prediction across six held-out-perturbation benchmarks, and its learned units recover interpretable biological response programs.
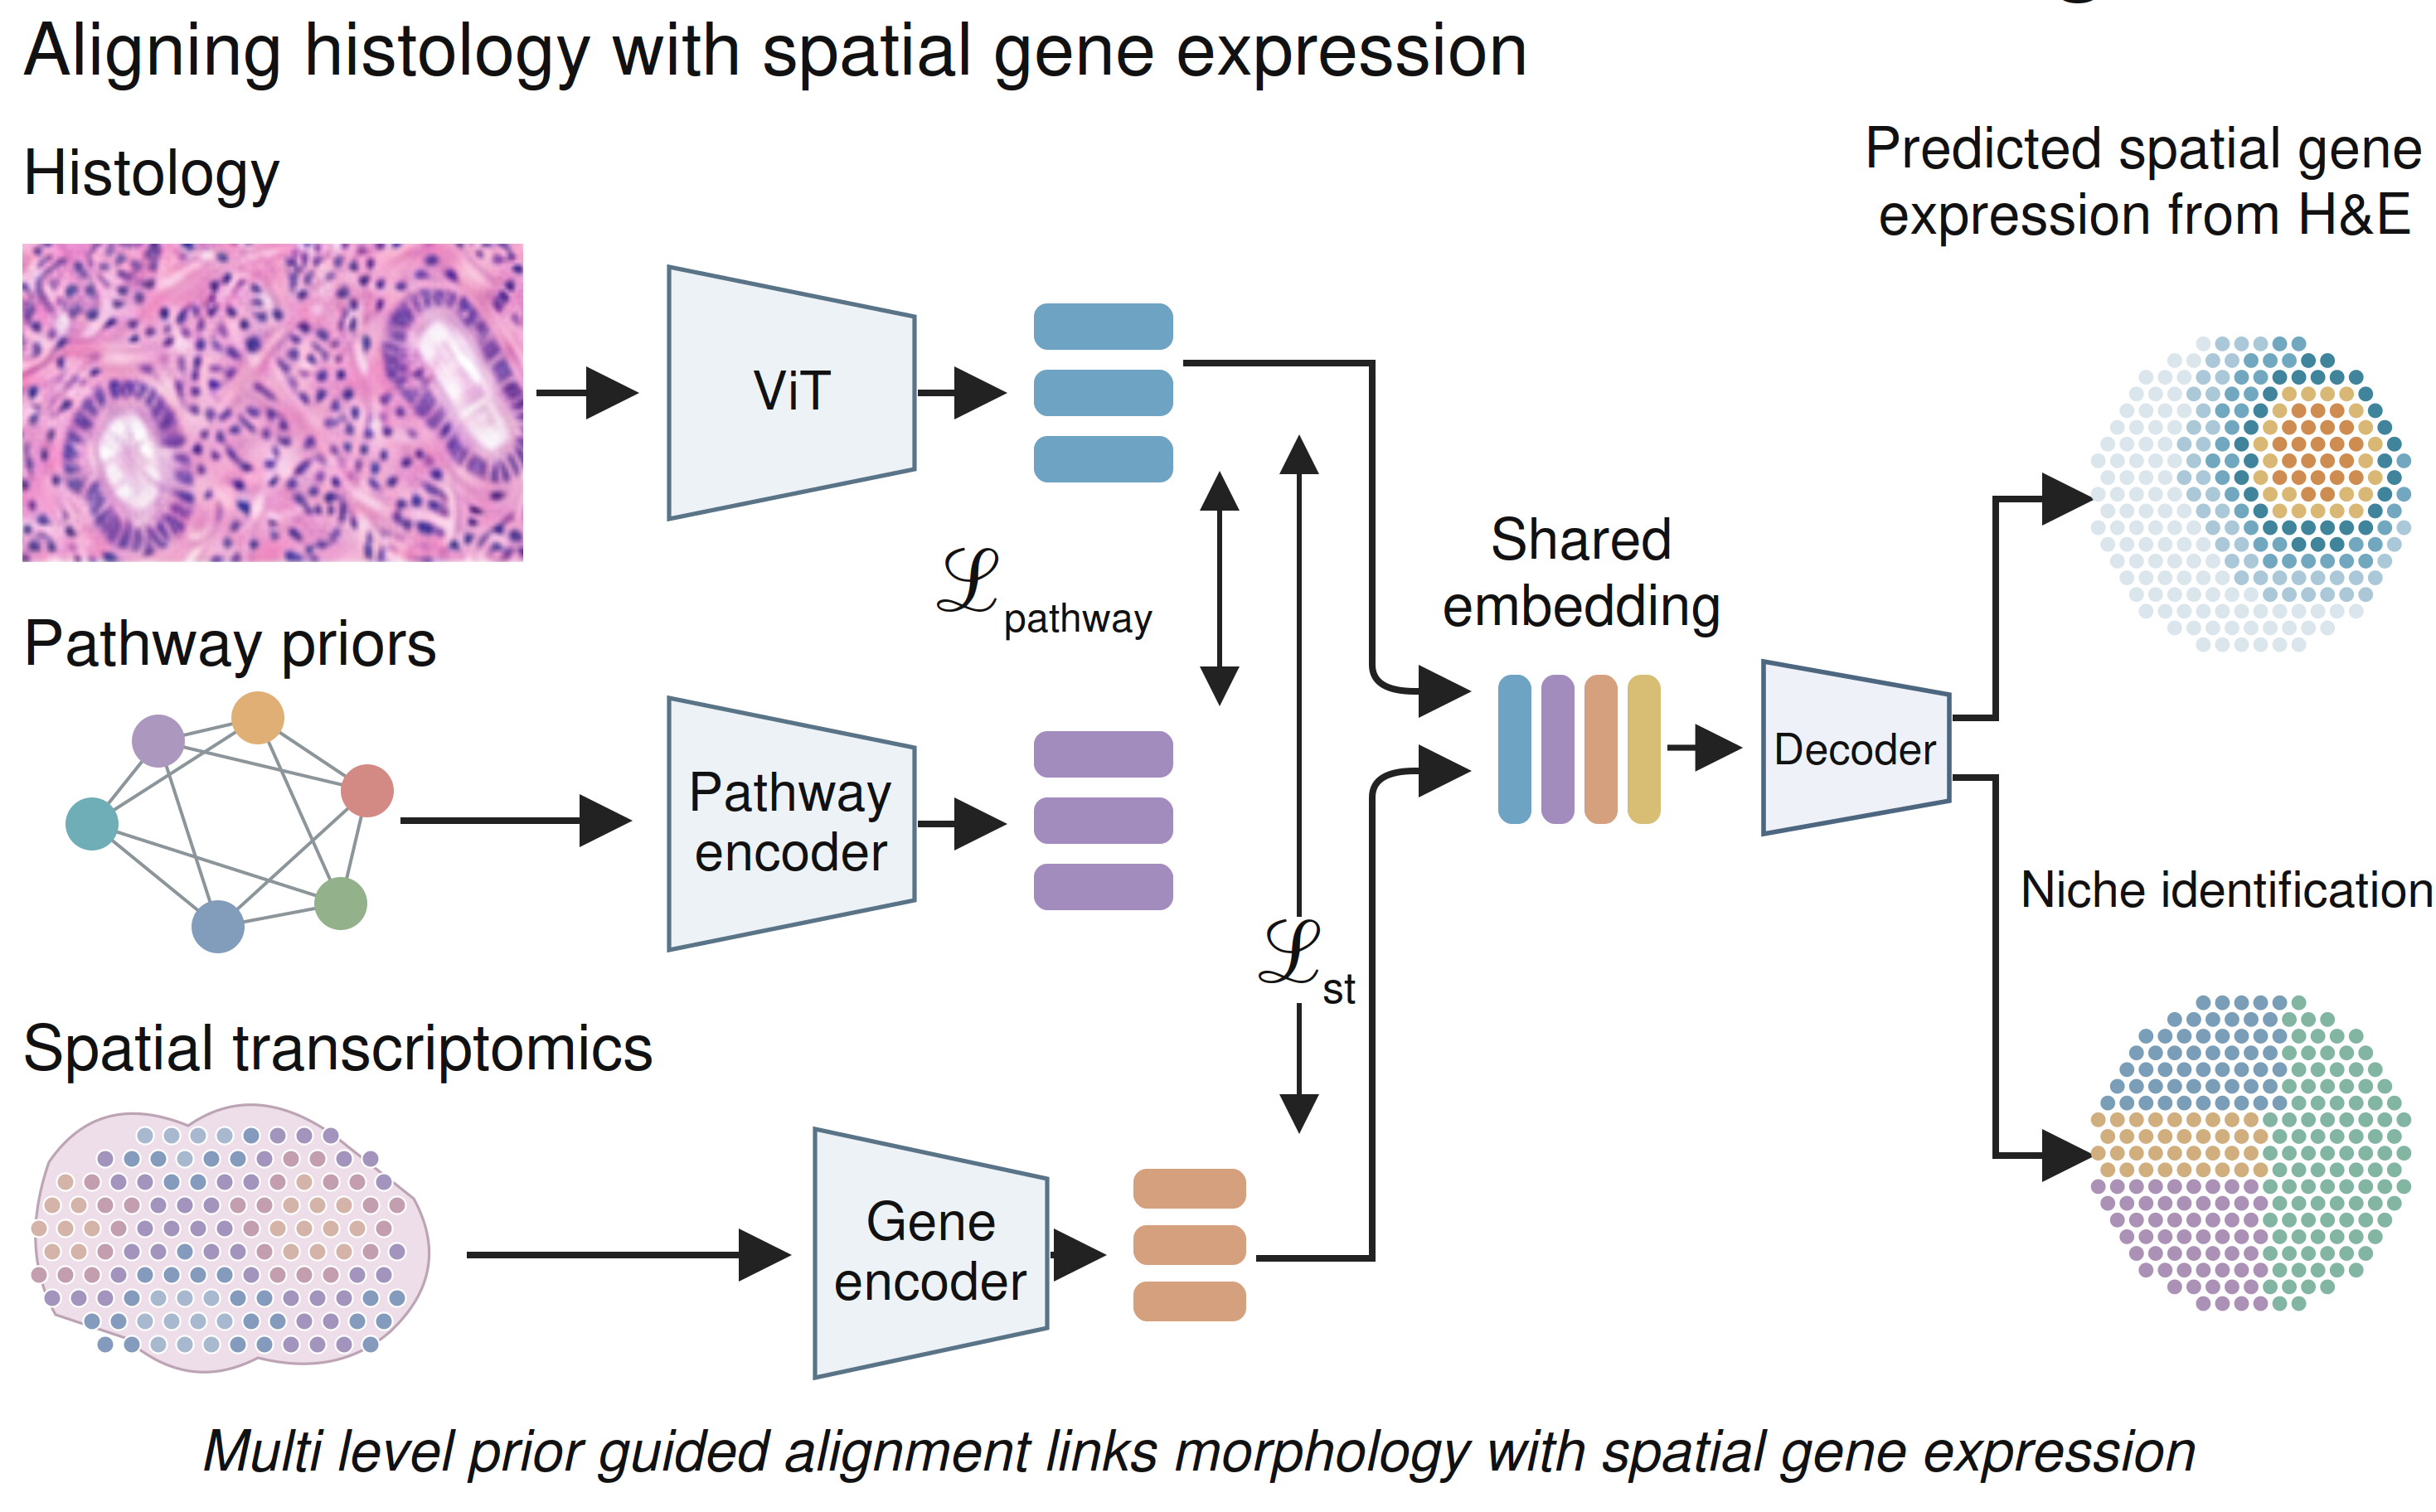
Spatial transcriptomics measures gene expression while keeping its location in the tissue, connecting what tissue looks like to what its cells are doing. PaSTel learns joint representations of histology images and gene expression by adding biological knowledge at three levels: emphasizing informative genes over housekeeping genes, anchoring to known biological pathways, and modeling how neighboring regions form tissue structure. PaSTel outperforms existing models across multiple downstream tasks.
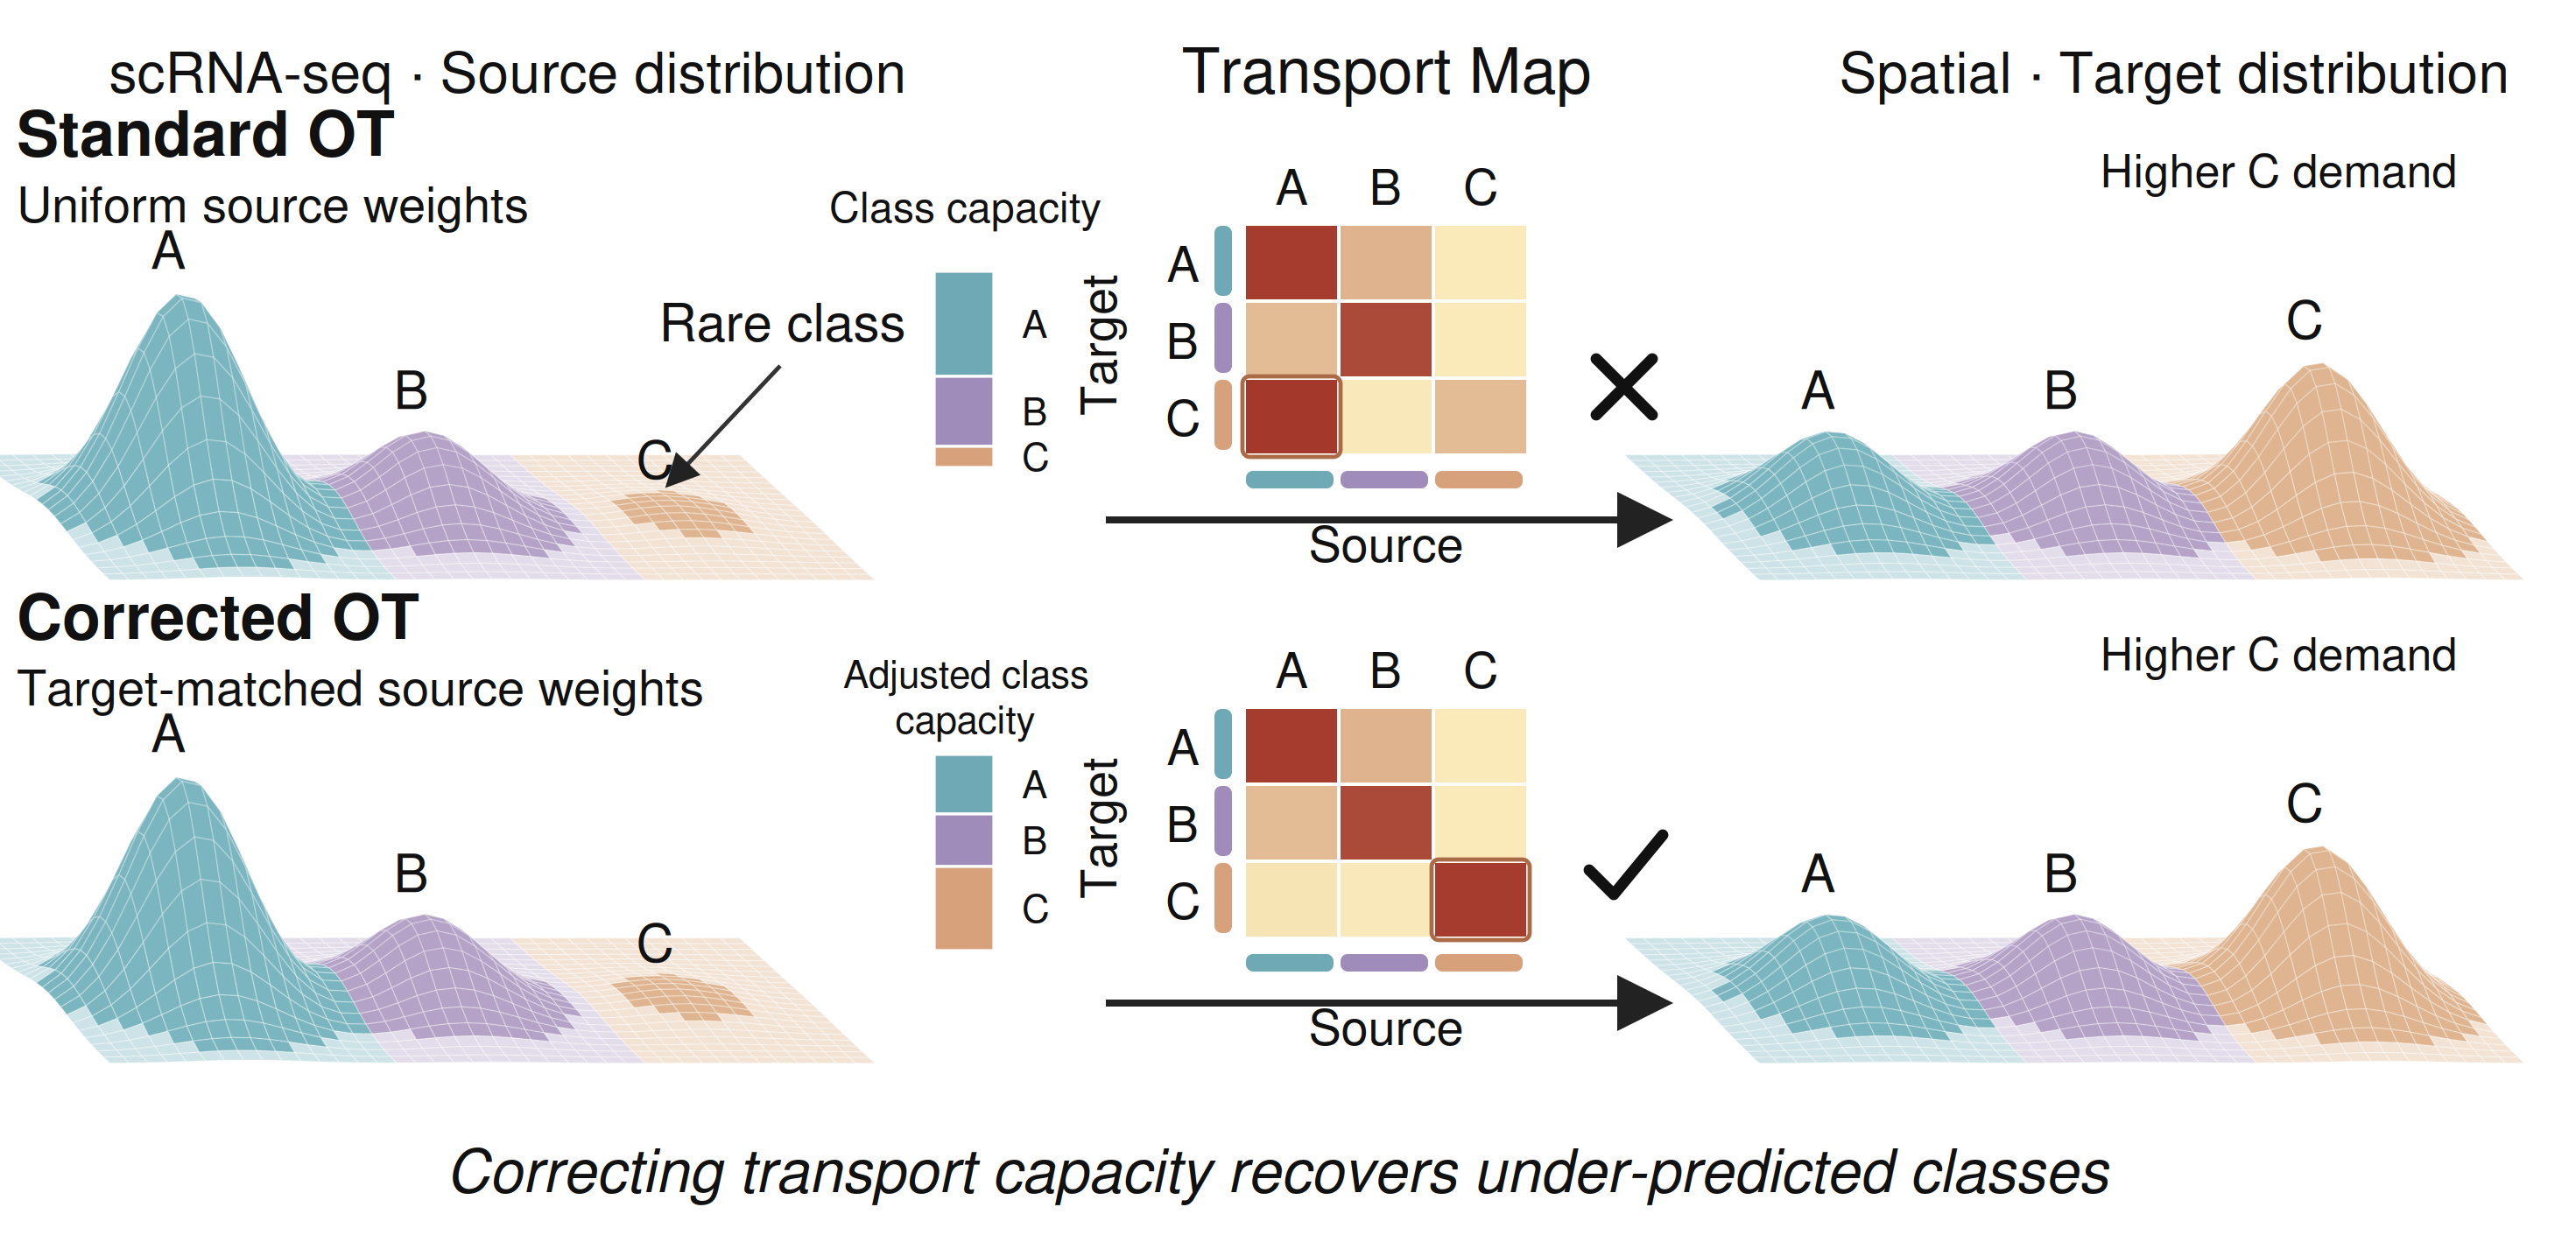
Optimal transport (OT) is a common way to transfer labels between datasets, such as annotating spatial data using a labeled single-cell reference. When the two datasets have different cell-type compositions, OT systematically misses rare classes, and these errors are hard to detect because the model remains confident. We show the cause is that each class can only send as much "mass" as it has in the source data, so rare classes run out of capacity. Matching this capacity to the target composition nearly doubles macro-F1 on single-cell data (0.32 to 0.62). This also separates errors caused by limited capacity from errors caused by poorly separated classes.
Cellular states are shaped by intrinsic gene expression programs and the surrounding spatial microenvironment. Spatial transcriptomics makes this context measurable, but effective representation learning must capture both spatially informative molecular signals and intercellular organization. Existing approaches can overlook spatially structured genes or encode cell–cell relationships using proximity alone or absolute coordinates, obscuring differences in local tissue organization.
We introduce Tessera, a spatial representation learning framework that combines spatially informed gene selection with a geometric inductive bias to contextualize each cell within its local tissue environment. Tessera models relative cell–cell relationships, preserving direction while remaining translation-invariant, so neighboring cells contribute differently according to their spatial context and cellular state. Across held-out tissues and technologies, Tessera outperforms existing spatial foundation models in representation quality and generalizes zero-shot to contexts up to 16× larger than those seen during training.
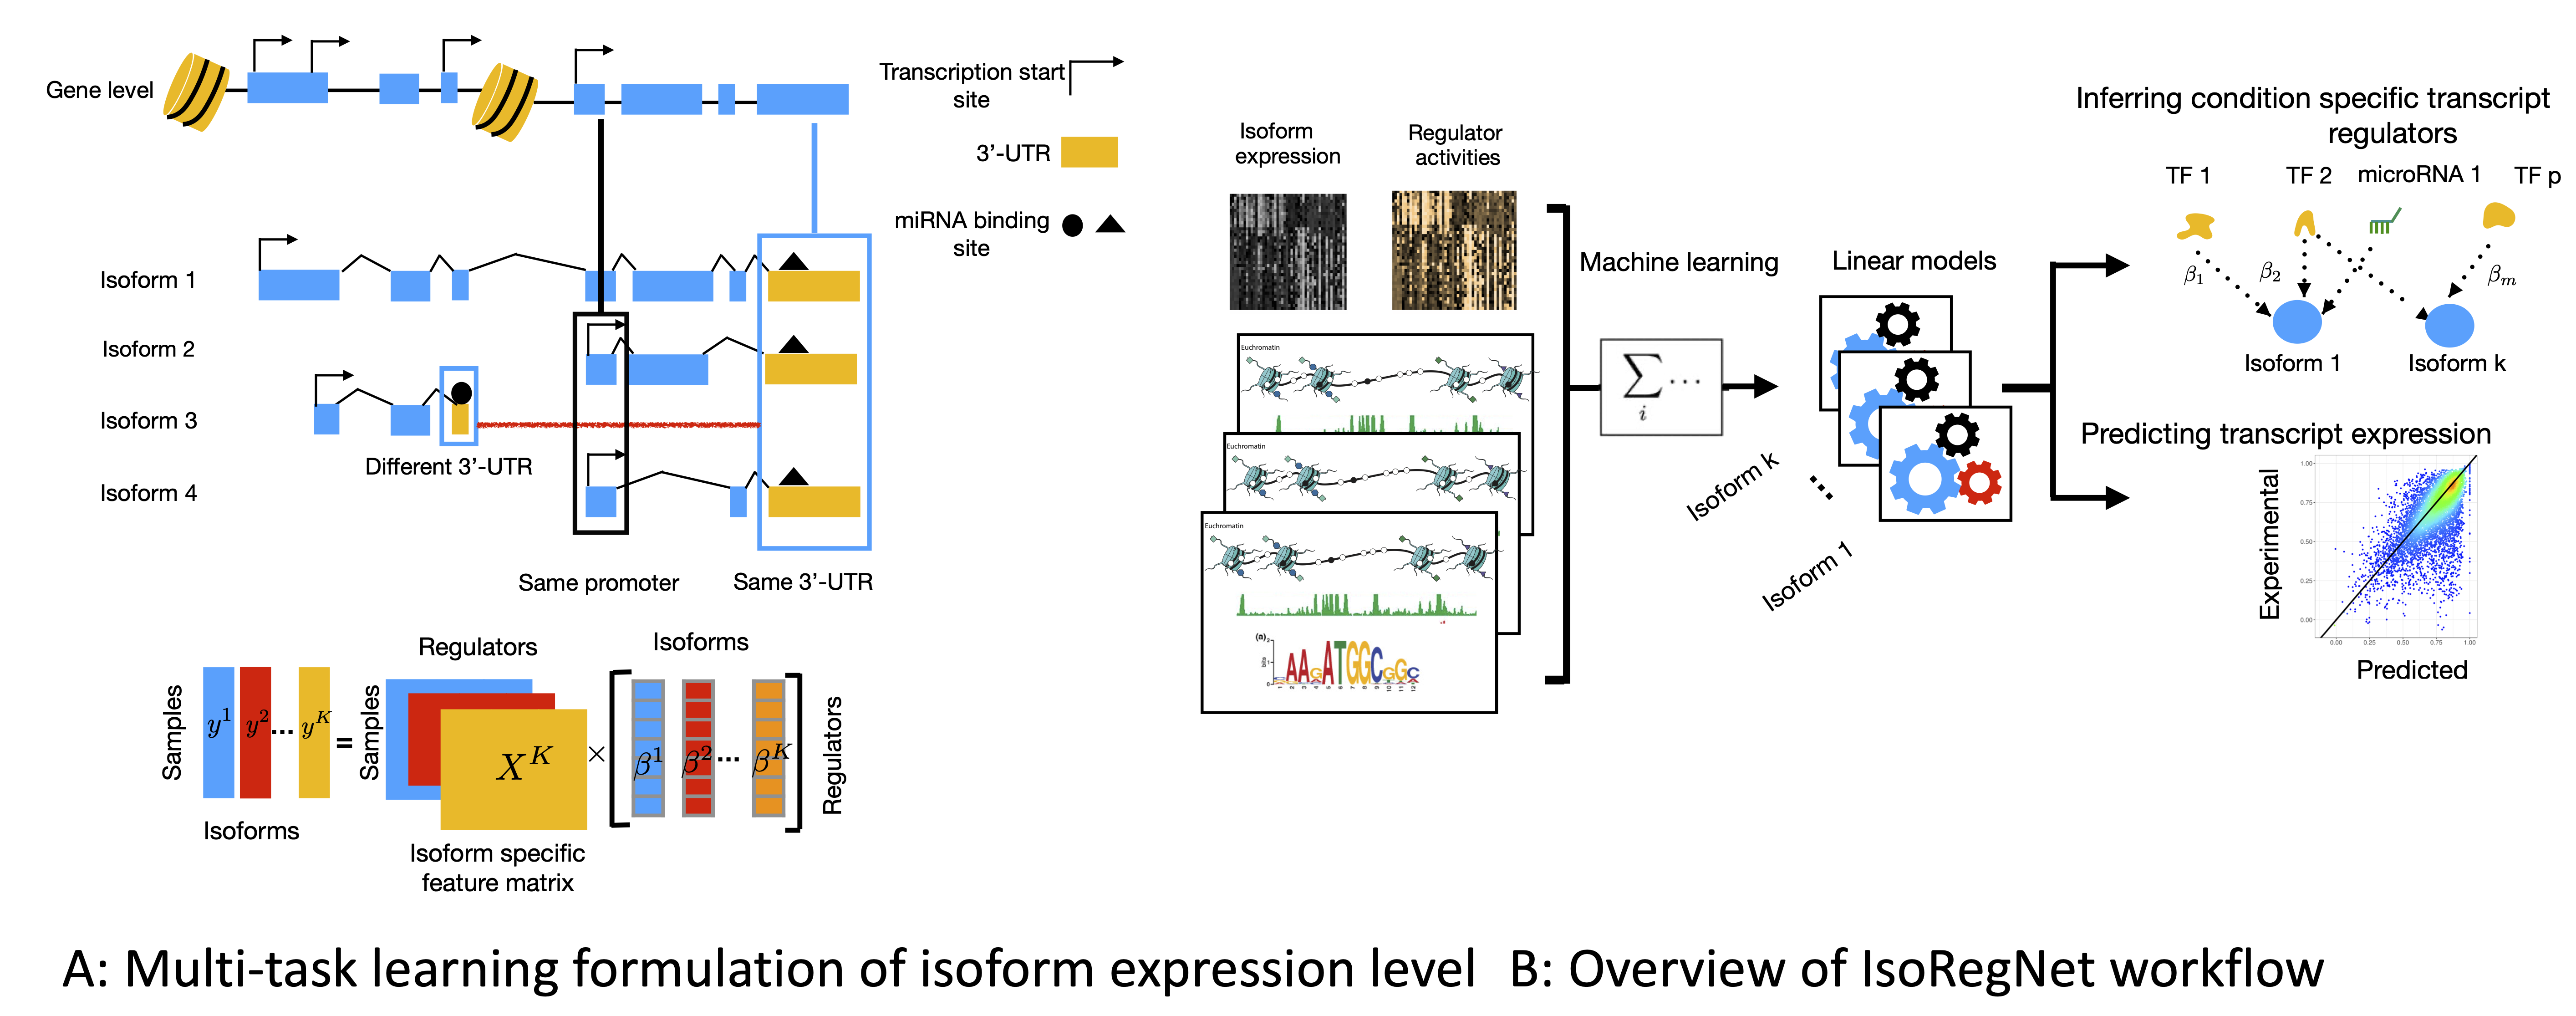
Understanding gene regulation is an important aspect in the context of cell differentiation, disease and environmental changes. Due to the complexity of gene regulation, methods for the inference of gene regulatory networks (GRNs) are often limited to one type of regulator, for example only DNA binding transcription factors or microRNAs. Also the diversity in gene isoforms is rarely taken into account during the construction of GRNs. I've developed a novel principled approach that allows to learn associations between transcriptional and post-transcriptional regulators with genes or their transcript isoforms. Using a novel multi-task formulation we design a regression framework, which allows to overcome some of the noise in isoform expression level estimates, leading to accurate predictions.
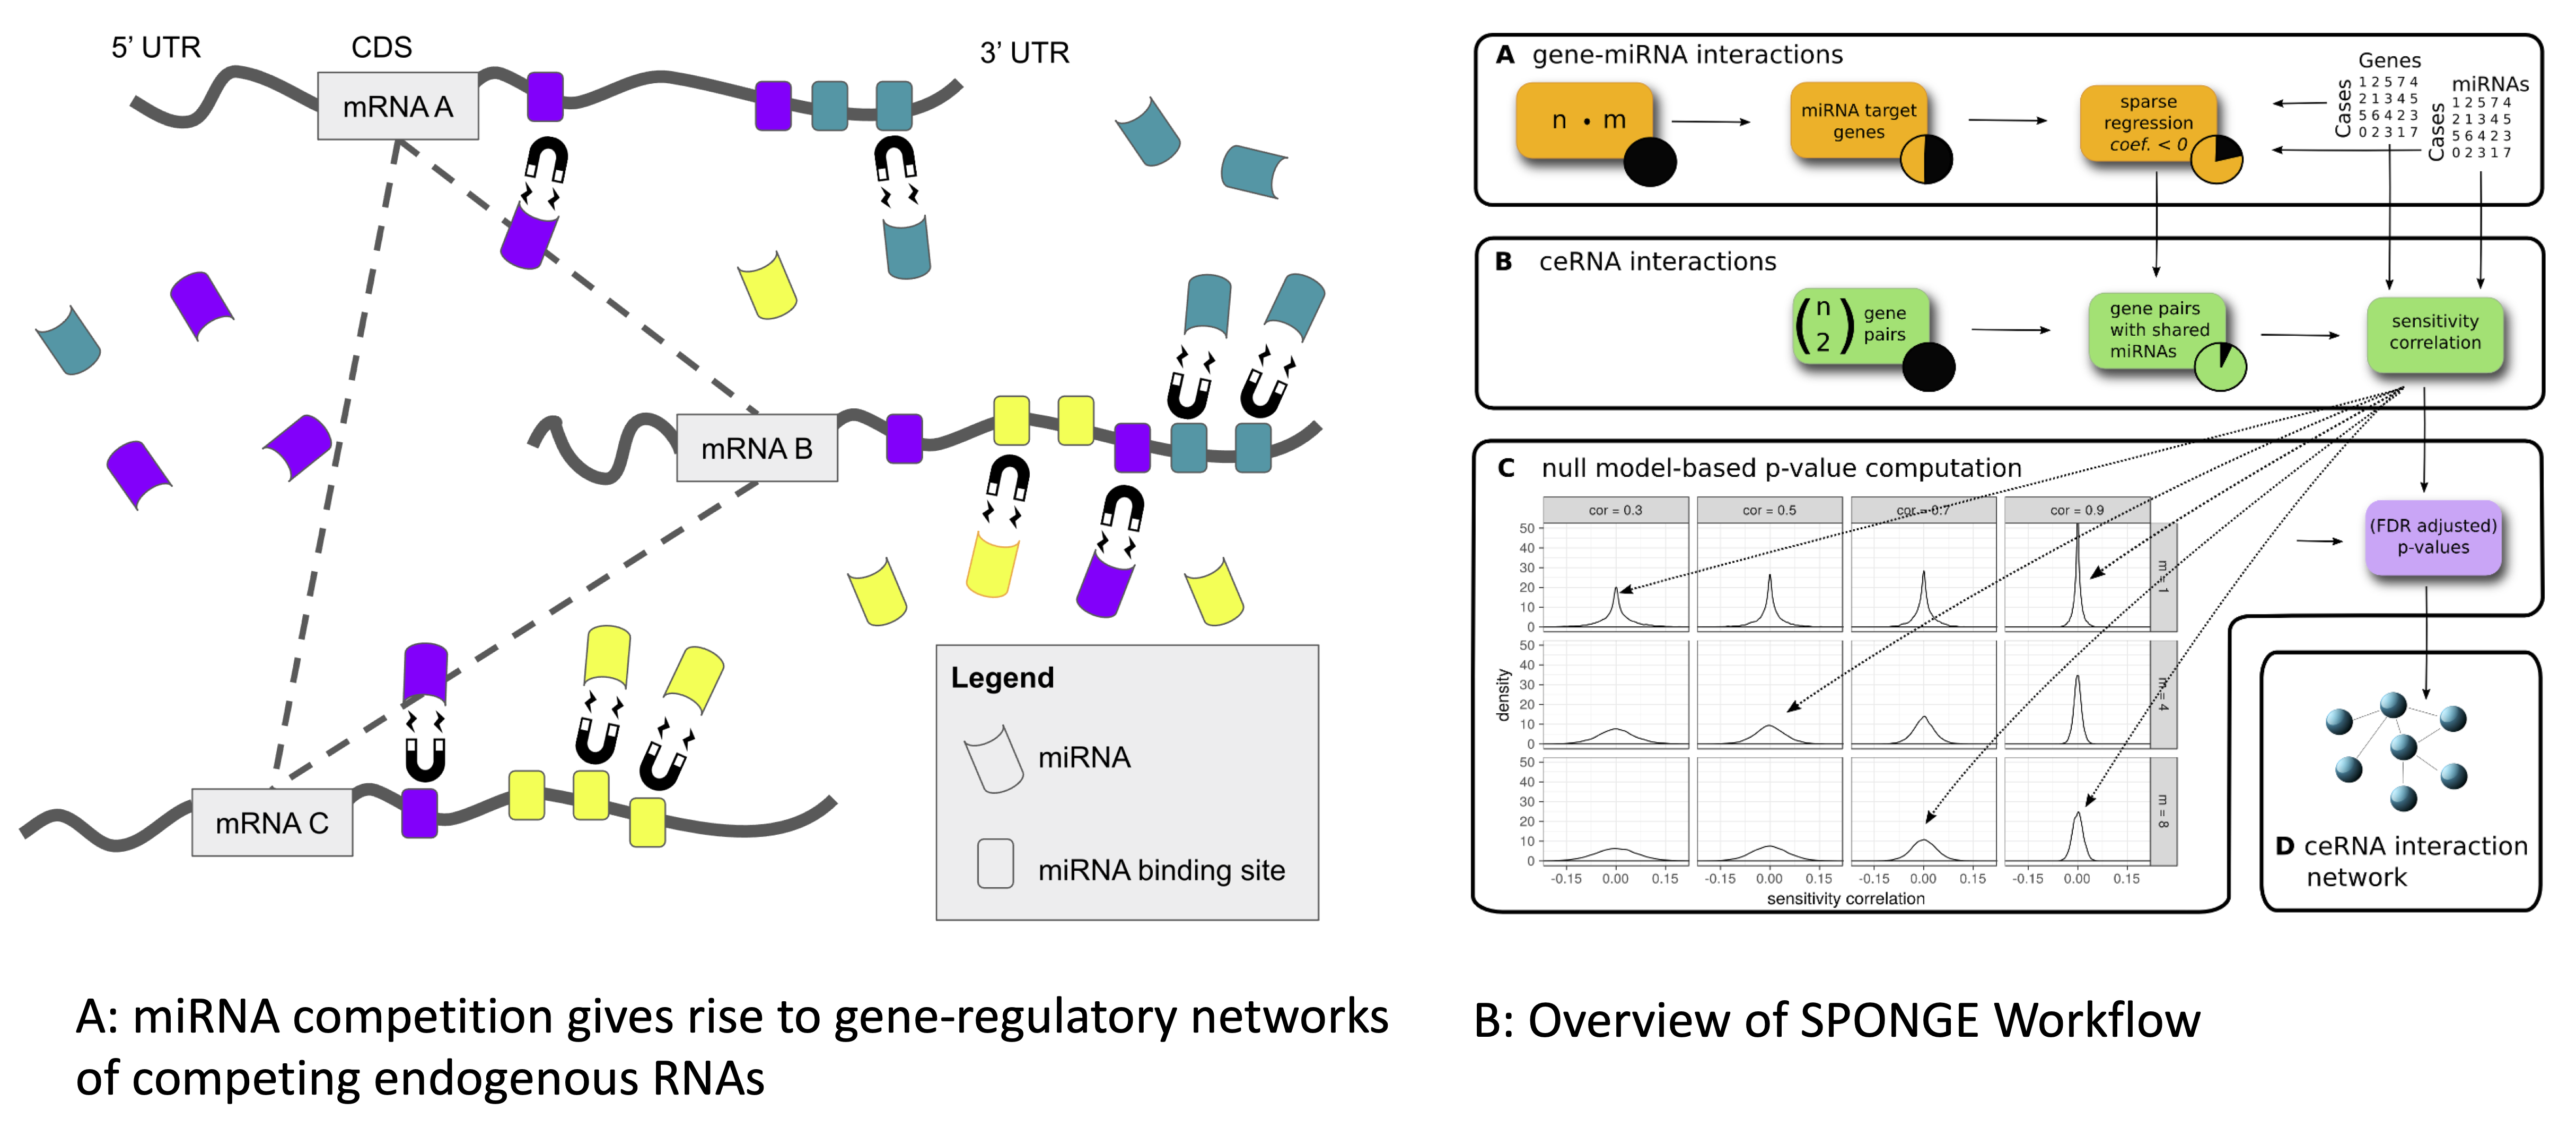
MicroRNAs (miRNAs) are important non-coding post-transcriptional regulators that are involved in many biological processes and human diseases. Individual miRNAs may regulate hundreds of genes, giving rise to a complex gene regulatory network in which transcripts carrying miRNA binding sites act as competing endogenous RNAs (ceRNAs). Several methods for the analysis of ceRNA interactions exist, but these do often not adjust for statistical confounders or address the problem that more than one miRNA interacts with a target transcript.
We developed SPONGE, a method for the fast construction of ceRNA networks. SPONGE uses multiple sensitivity correlation, a newly defined measure for which we can estimate a distribution under a null hypothesis. SPONGE can accurately quantify the contribution of multiple miRNAs to a ceRNA interaction with a probabilistic model that addresses previously neglected confounding factors and allows fast P-value calculation, thus outperforming existing approaches. We applied SPONGE to paired miRNA and gene expression data from The Cancer Genome Atlas for studying global effects of miRNA-mediated cross-talk. Our results highlight already established and novel protein-coding and non-coding ceRNAs which could serve as biomarkers in cancer.